Scaling and restarting
Scaling
Section titled “Scaling”Deployments and StatefulSets are the two kinds that scale, from their detail pages and from their lists.
On a Deployment’s or a StatefulSet’s detail page, Scale sits in the header beside Restart. It
opens Scale Deployment (or Scale StatefulSet) with a Replicas field, filled in with the
current count, and Scale and Cancel. Enter in the field scales too. Any whole number from
0 to 1000 is accepted; Scale stays disabled until the number differs from the current one.
In the lists, each row has a Scale column: Scale down (−), the current count and Scale up (+), joined in one group. A step sets the count one lower or higher. Hovering the row shows one more button beside the group, which opens the same Replicas field for an exact number; it is there for the keyboard too, as the next stop after Scale up.
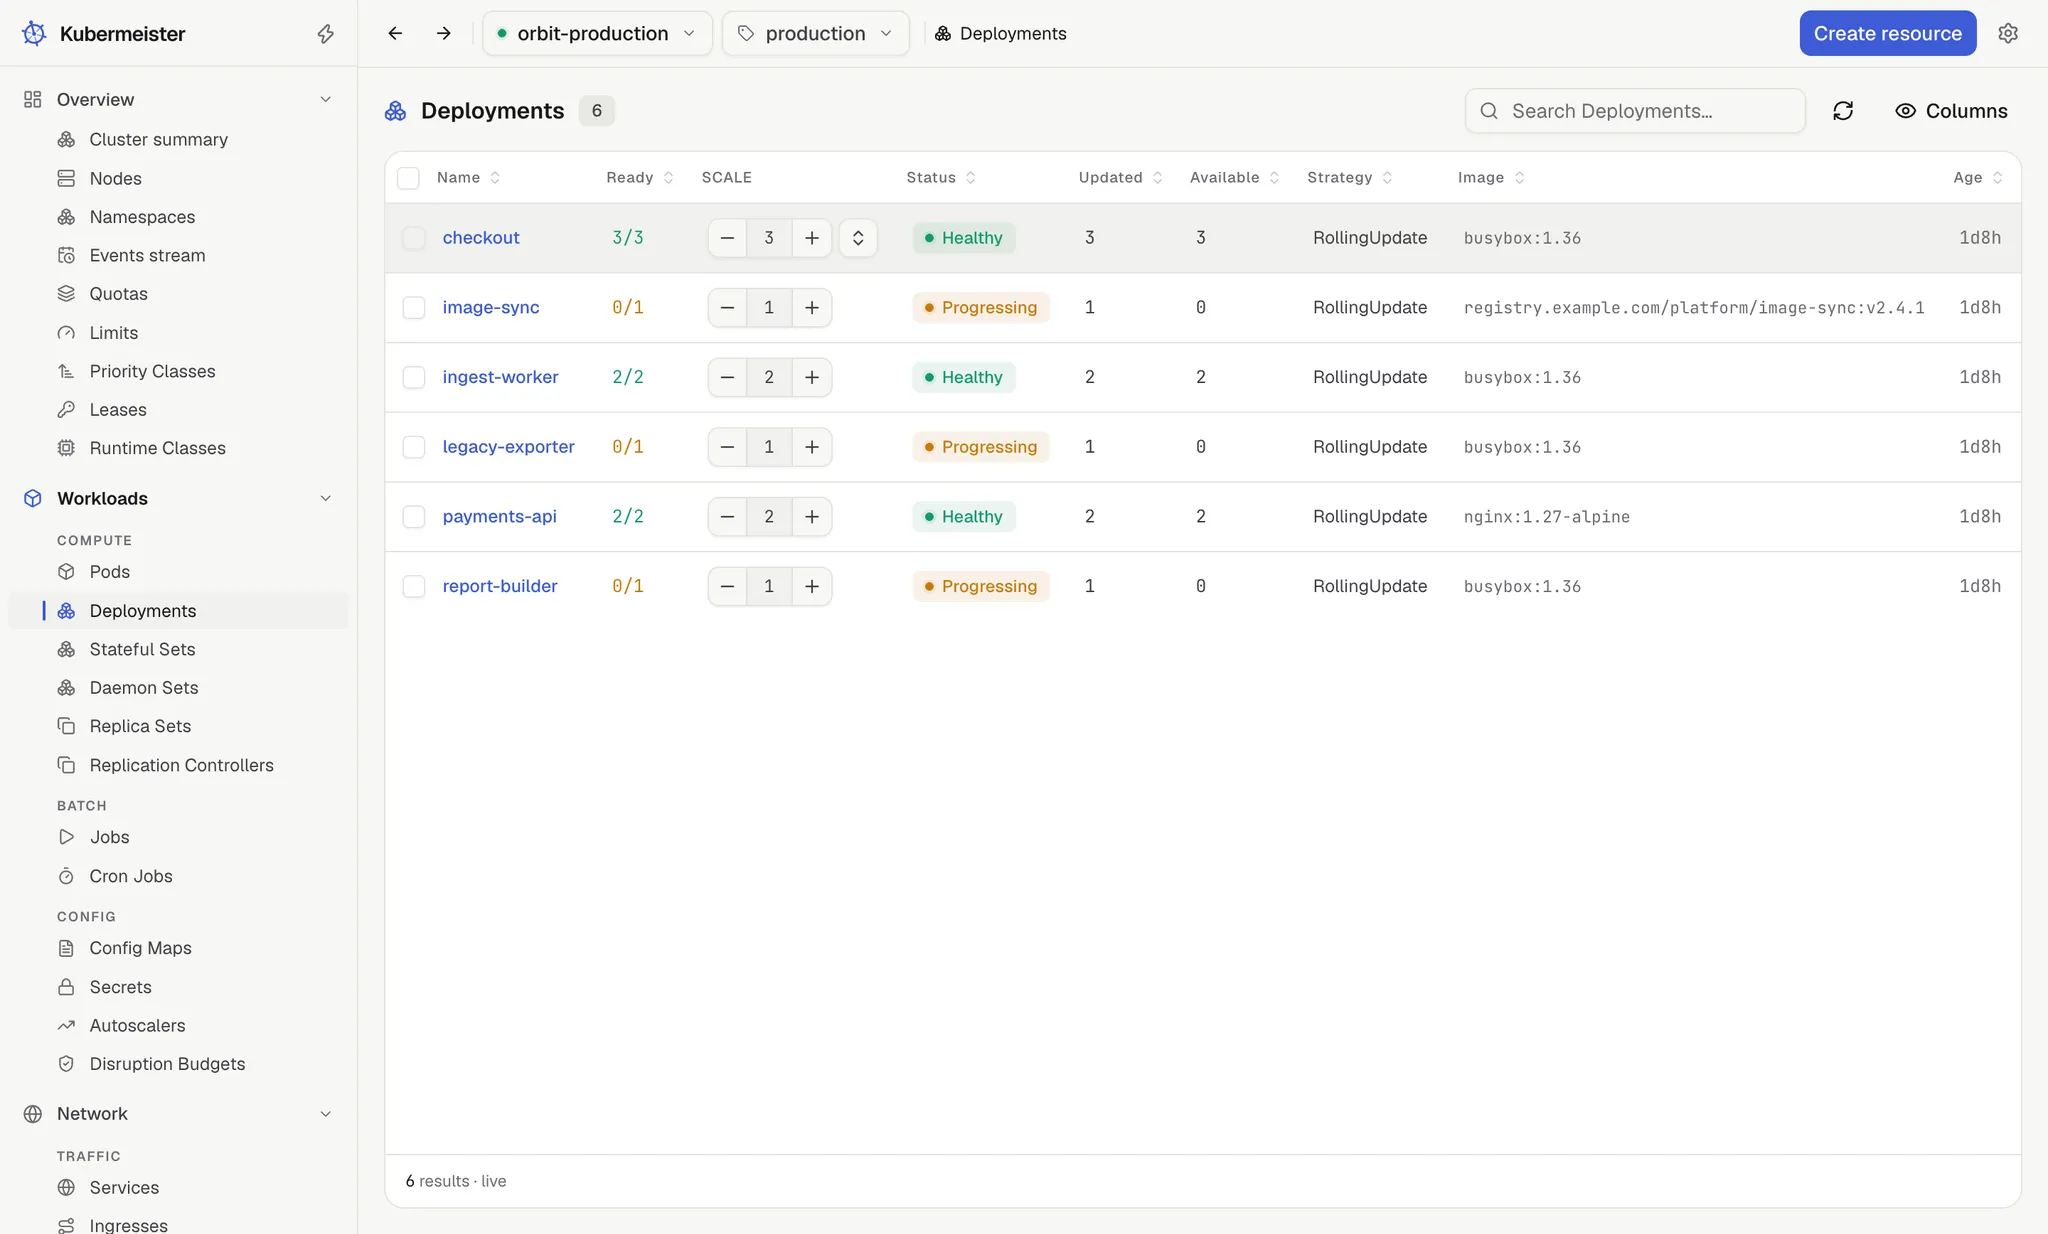
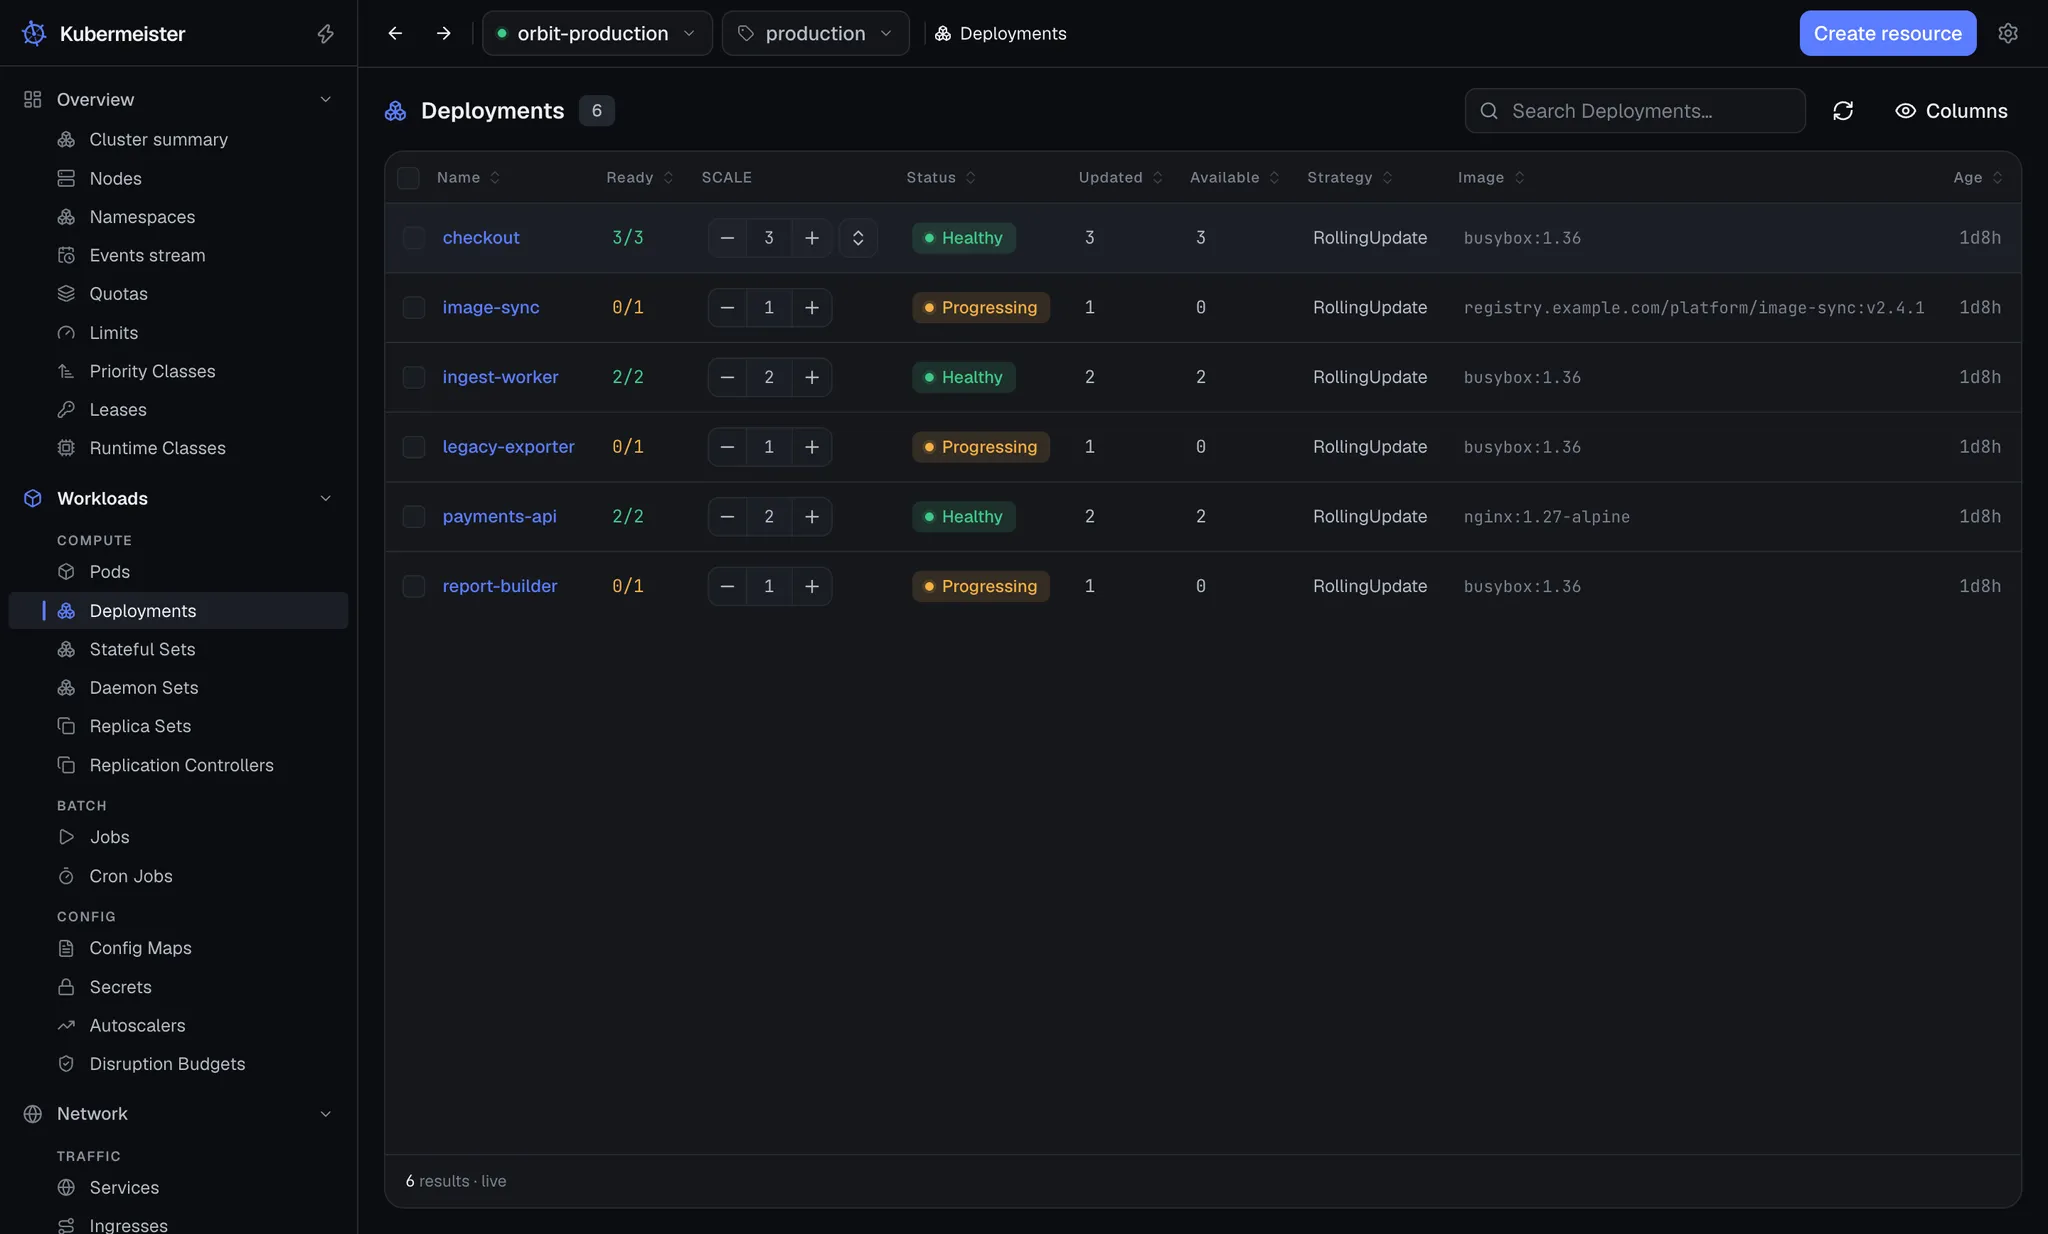
Each step writes the absolute target, not a delta, and both steppers go inert while a write is in
flight, so rapid clicks cannot race each other. The write reads the scale subresource first and puts
it back with the resourceVersion it was read at, so a change somebody else made in between is
rejected as a conflict rather than overwritten.
Restarting
Section titled “Restarting”Restart sits in the header of a Deployment, a StatefulSet and a DaemonSet. It asks “Restart Deployment?” (or the kind in question) and says how the pods will go:
| Kind | What the dialog says |
|---|---|
| Deployment | Pods are replaced gradually, following the deployment’s update strategy. |
| StatefulSet | Pods are replaced one at a time, in reverse ordinal order. |
| DaemonSet | The pod on each node is replaced, following the daemon set’s update strategy. |
A restart is a strategic merge patch stamping the pod template’s
kubectl.kubernetes.io/restartedAt annotation — the same key kubectl rollout restart writes, so
both read as one history. Nothing is deleted: the controller rolls the pods itself, at the kind’s own
update strategy.
Restarting from a pod
Section titled “Restarting from a pod”A pod’s Overview has its own Restart, which rolls the Deployment, StatefulSet or DaemonSet that owns the pod, because a pod deleted on its own simply comes back unchanged. Hovering it names the workload it will roll (“Rolls Deployment “web”, replacing this pod”).
This one asks for no confirmation: a click starts the rollout of the whole workload at once. A pod with no such owner — a bare pod, one owned by a Job, or one owned by a custom resource that shares a built-in kind’s name, such as an OpenKruise StatefulSet — shows the button disabled with “This pod has no workload to roll”.
Autoscalers
Section titled “Autoscalers”A HorizontalPodAutoscaler’s detail page has Edit bounds in its header. It opens Autoscaler bounds with three fields: Minimum replicas, Maximum replicas and Target CPU %, each filled in with the autoscaler’s current values, and Save.
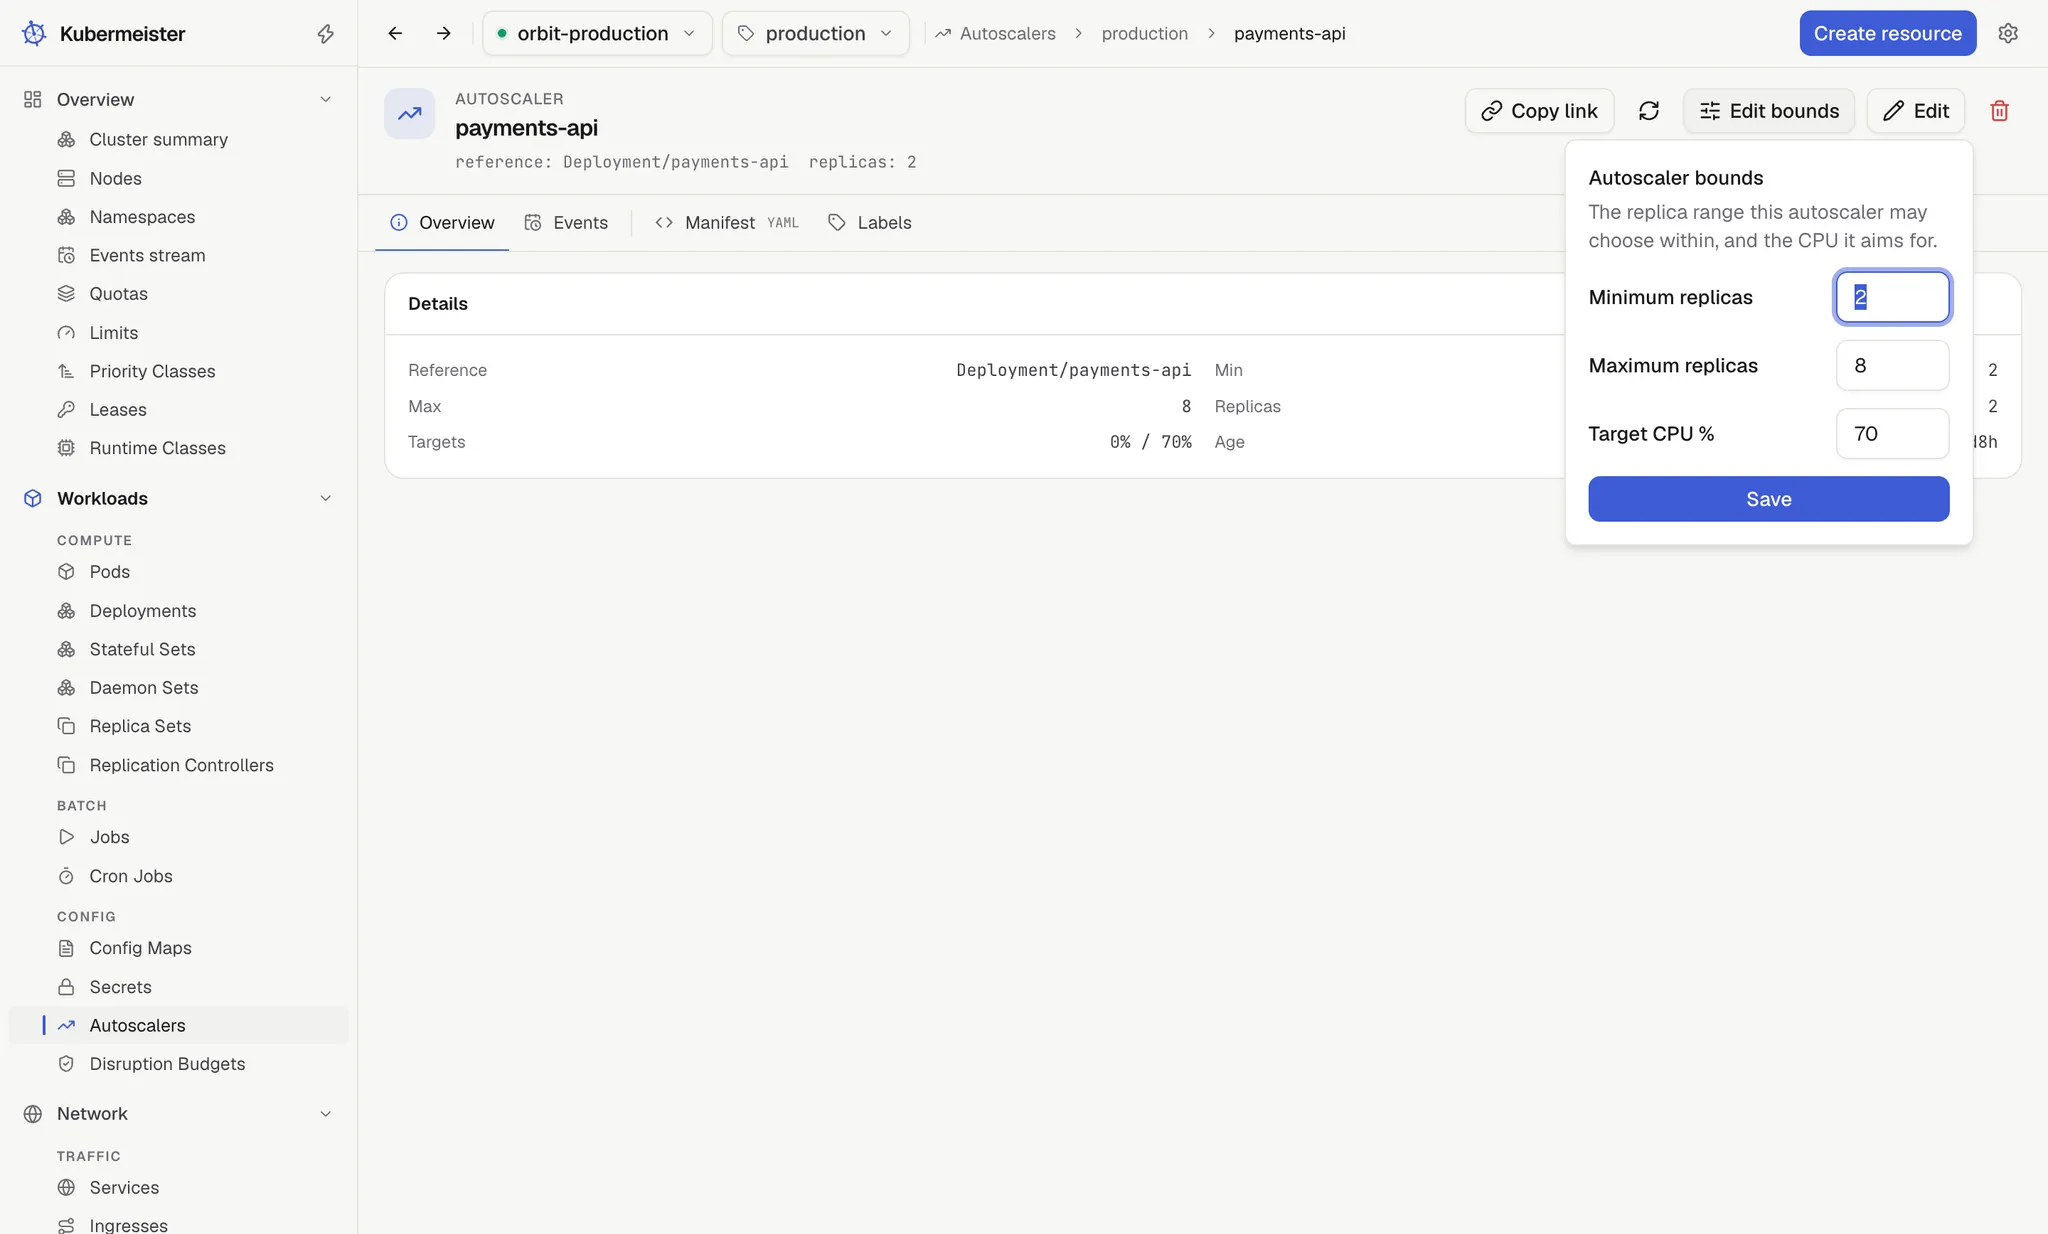
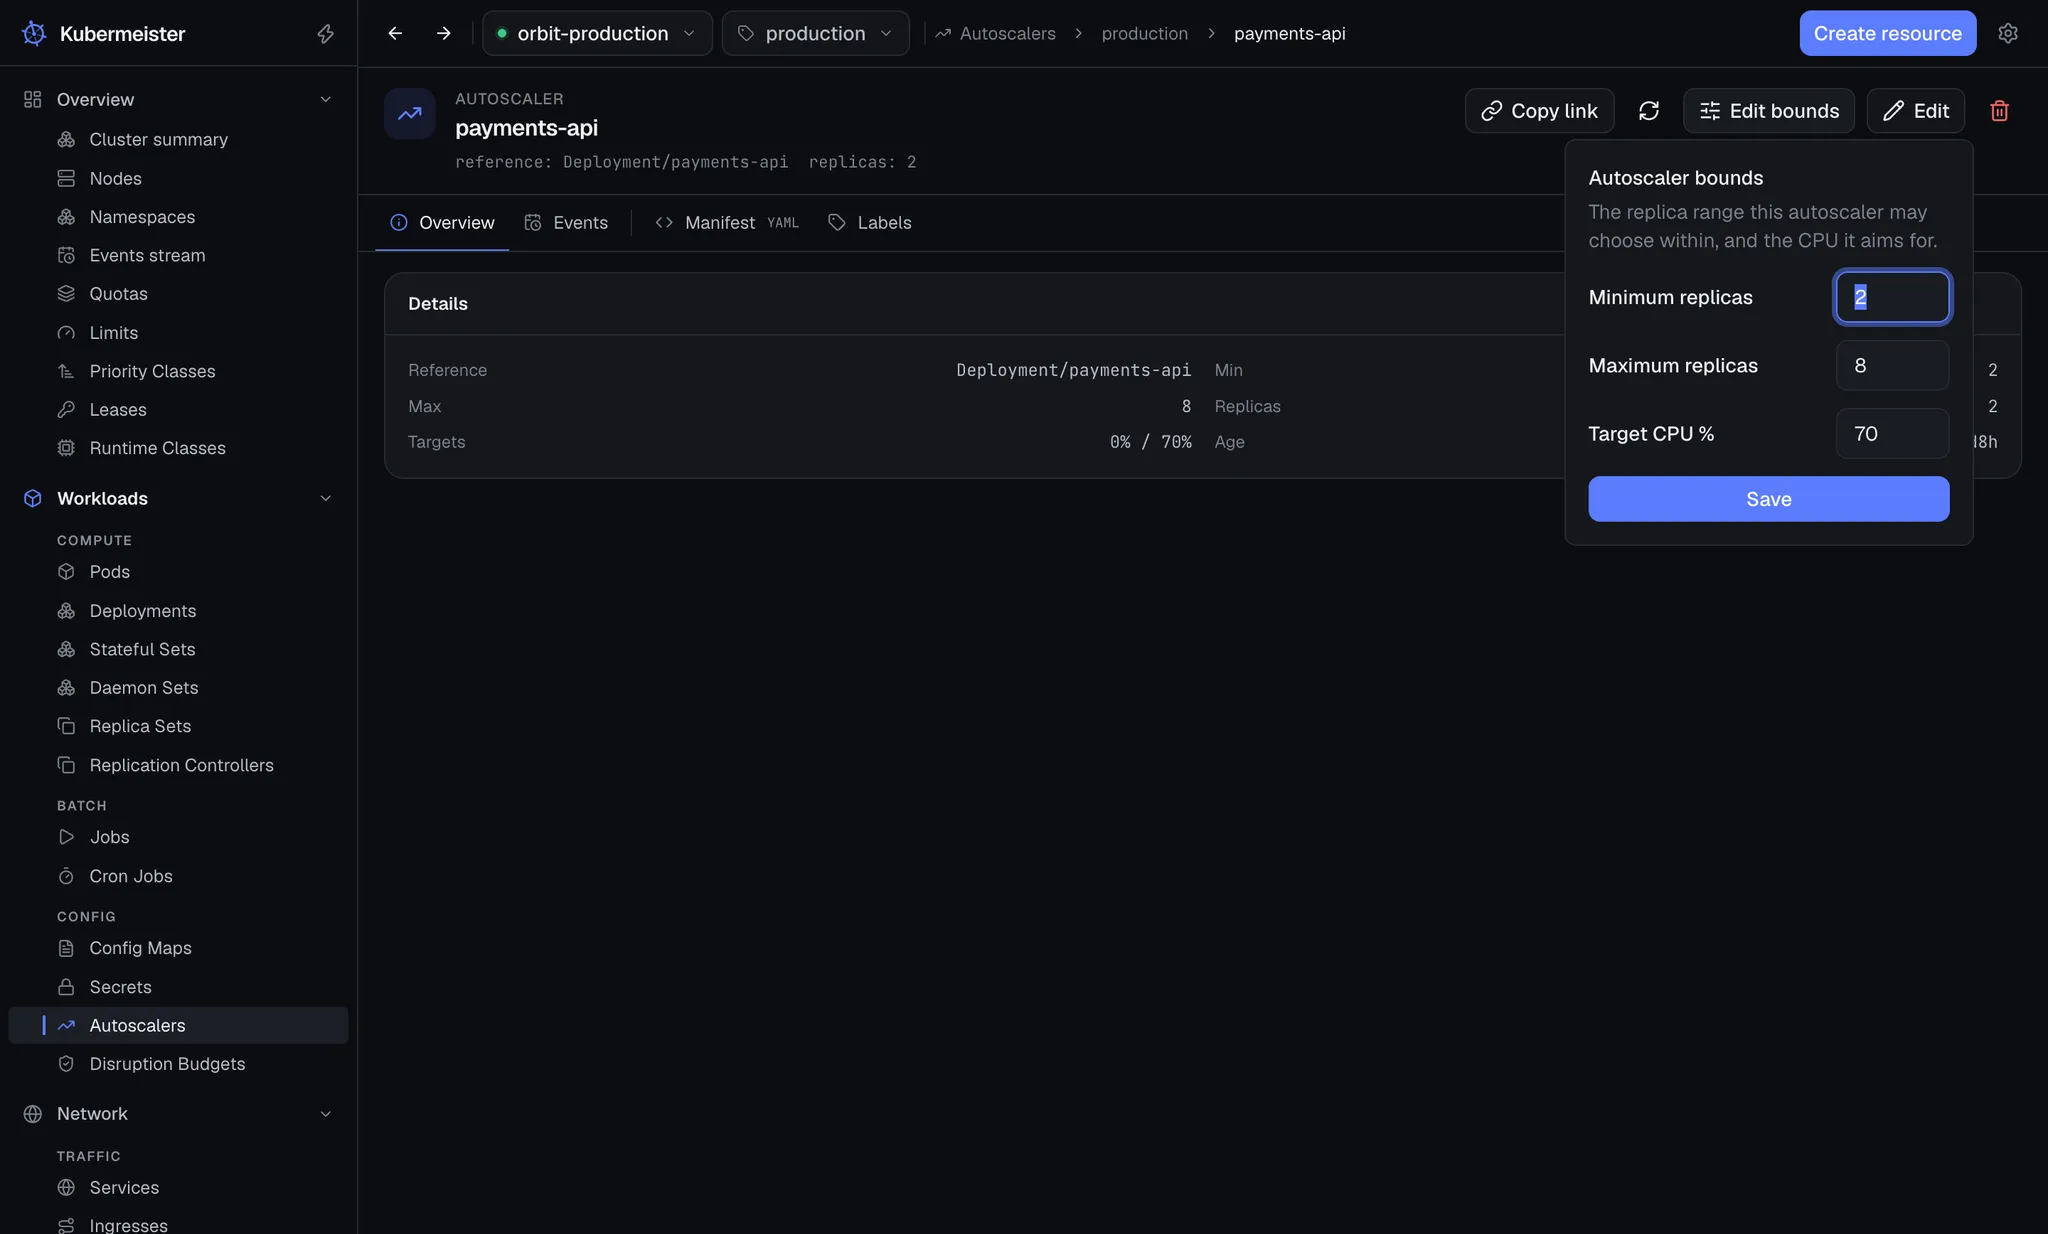
Save stays disabled until both counts are whole numbers, the minimum is at least one and the
maximum at least the minimum (“The maximum must be at least the minimum, and both at least one.”).
The CPU target, when given, must be a whole number of at least one; an autoscaler with no CPU target
shows the field empty (—).
Save writes the bounds, and writes the CPU target only when you changed it. Changing it replaces just the autoscaler’s CPU utilisation target: memory, custom and external metrics it also watches stay as they were, and an autoscaler with no CPU target gains one after the metrics it already has. If the autoscaler was changed by someone else between opening the popover and saving, the save is refused as a conflict rather than overwriting their change.
Anything else about an autoscaler — which metrics it watches, its scaling behaviour — is edited in the manifest editor.
Evicting and deleting pods
Section titled “Evicting and deleting pods”A pod’s header has Evict as well as delete. Evict asks “Evict pod?” and goes through the eviction API, the way a node drain does, so a PodDisruptionBudget still has a say and may refuse it. A plain delete does not consult budgets.
The pod’s delete dialog also offers Delete without waiting (“The record goes at once, whatever the container is still doing.”), which sends a grace period of zero. Only pods get that switch; for any other kind the grace period is left to the controller. See writing to the cluster for what every delete asks.